Note
Go to the end to download the full example code.
Hydropower: worldwide historical coverage and evidence gaps#
Rebuild the WRI Global Power Plant Database hydro partition offline as typed Parquet and map its reported coordinates. CC BY 4.0 attribution: World Resources Institute, GPPD v1.3.0 repository snapshot. WRI stopped maintenance in early 2022. This is historical discovery coverage, not a current operating census or a ranking of installed national capacity. 110 Norwegian records have reviewed NVE lifecycle and technical enrichment; 1175 US records carry dated 2025 EIA inventory. 177 Brazilian records retain ONS registry/unit evidence and structured state/subsystem metadata. 13 Indian records retain reviewed historical IHA station evidence. 84 African records retain AHA river/basin evidence and explicit historical/model field bases. Three New Zealand records retain reviewed dispatch connection evidence. Twelve New Zealand identities also carry 59 owner technical assertions. Unit and station ratings stay separate. Eight Brazilian records are new CEG identities, including two small hydro plants. Their coordinates and current lifecycle remain unknown. Thirteen Kenyan identities carry owner-reported fiscal 2021-2025 statistics. Effective MW and sold GWh are separate from installed MW and generation. Thirty-two new Ugandan identities retain ERA annual MW statistics through September 2026. Missing cells and explicit zeros remain distinct; unknown locations are not mapped. Nepal DoED licences retain reported MW separately from installed/operating capacity. Source bounds are not mapped as plant points; page-date and retrieval-date bases stay distinct. Twelve SNEL stations retain 2015 observations, including five new historical identities. Average available MW is separate from installed MW; gross MWh is converted exactly to GWh. Pumped storage is not inferred from names. See the interactive hydro viewer for source evidence.
import json
from pathlib import Path
from tempfile import TemporaryDirectory

import matplotlib.pyplot as plt
import pandas as pd

from energy_data_retrieval.hydro_catalogue import build_parquet, capacity_summary, load_records

ROOT = next(p for p in (Path.cwd(), *Path.cwd().parents) if (p / "catalogues/hydro").is_dir())
rows = load_records(ROOT / "catalogues/hydro")
with TemporaryDirectory() as folder:
    snapshot = Path(folder) / "snapshot"
    manifest = build_parquet(ROOT / "catalogues/hydro", snapshot)
    plants = pd.read_parquet(snapshot / "projects.parquet")
print("Canonical records:", len(plants), "Countries:", plants.country_code.nunique())
print("NVE-enriched operating records:", sum("nve-hydro-20261105" in r["sources"] for r in rows))
print(
    "EIA year-end 2025 enriched records:",
    sum(any(s.startswith("eia860-2025-hydro-") for s in r["sources"]) for r in rows),
)
print(
    "ONS Brazil records (existing enriched + new registry identities):",
    sum(any(s.startswith("ons-hydro-") for s in r["sources"]) for r in rows),
)
print(
    "IHA India enriched records:",
    sum(any(s.startswith("iha-india-") for s in r["sources"]) for r in rows),
)
print(
    "AHA Africa enriched records:",
    sum(any(s.startswith("aha-v2.3-") for s in r["sources"]) for r in rows),
)
print("NZ reviewed dispatch identities:", sum("nz-ea-fleet-20260702" in r["sources"] for r in rows))
print(
    "AHA records with explicit field bases:",
    sum("aha_field_provenance" in json.loads(r["extensions_json"]) for r in rows),
)
print(
    "ERA Uganda reviewed identities:",
    sum("uganda-era-capacity-202609" in r["sources"] for r in rows),
)
print("Input fingerprint:", manifest["input_sha256"])
print("Reviewed installed generating MW:", capacity_summary(rows, "installed_capacity_mw"))
print("Pumping input MW (separate from generation):", capacity_summary(rows, "pumping_capacity_mw"))

print(
    "Reviewed powerhouse components:",
    sum(len(json.loads(r["extensions_json"]).get("ons_components", [])) for r in rows),
)

fig, axes = plt.subplots(1, 2, figsize=(13, 5), layout="constrained")
located = plants.dropna(subset=["latitude", "longitude"])
axes[0].scatter(located.longitude, located.latitude, s=4, alpha=0.4, color="#087e8b")
axes[0].set(
    xlim=(-180, 180),
    ylim=(-60, 85),
    xlabel="Longitude [degrees]",
    ylabel="Latitude [degrees]",
    title="Reported plant locations · historical WRI inventory",
)
axes[0].grid(alpha=0.2)
plants.country_code.value_counts().head(15).sort_values().plot.barh(ax=axes[1], color="#087e8b")
axes[1].set(
    xlabel="Historical plant records",
    ylabel="Country code",
    title="Coverage leaders, not capacity market share",
)
fig.suptitle("Global hydro coverage · dated NVE/EIA updates · capacity scope unresolved")
plt.show()
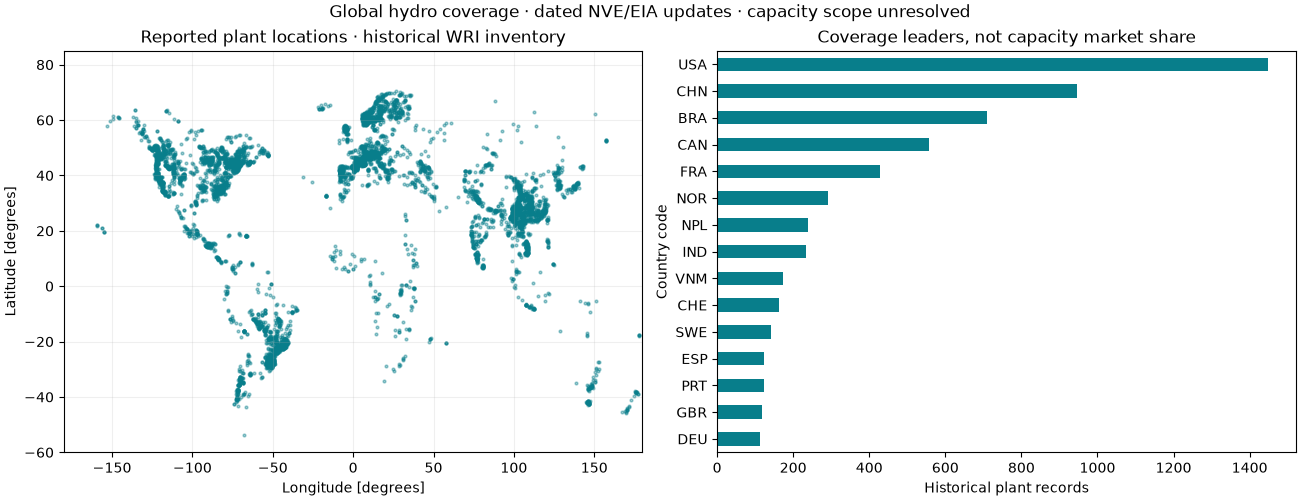
Canonical records: 7454 Countries: 128
NVE-enriched operating records: 110
EIA year-end 2025 enriched records: 1175
ONS Brazil records (existing enriched + new registry identities): 177
IHA India enriched records: 13
AHA Africa enriched records: 84
NZ reviewed dispatch identities: 3
AHA records with explicit field bases: 84
ERA Uganda reviewed identities: 32
Input fingerprint: 0768a48012b8caa81e3bf28501b4c86afd10dabfb7ef13f58e5c21375a456a68
Reviewed installed generating MW: {'excluded': 7454, 'unknown': 0, 'by_status': {}}
Pumping input MW (separate from generation): {'excluded': 7454, 'unknown': 0, 'by_status': {}}
Reviewed powerhouse components: 6
Dated owner observations, without substituting sales for generation.
kengen = [
    {"name": r["name"], **o}
    for r in rows
    for o in json.loads(r.get("observations_json") or "[]")
    if o["source_id"] == "kengen-annual-2025-20261106" and o["field"] == "annual_generation_gwh"
]
energy = pd.DataFrame(kengen)
print("KenGen dated generation observations:", len(energy))
fig, ax = plt.subplots(figsize=(9, 5), layout="constrained")
for name, group in energy.groupby("name"):
    group = group.sort_values("period")
    ax.plot(group.period.str.slice(9, 13), group.value, marker="o", label=name)
ax.set(
    xlabel="Fiscal year ended June 30",
    ylabel="Reported generated energy [GWh]",
    title="KenGen thirteen reviewed stations · historical owner statistics",
)
ax.legend(ncol=2, fontsize=8)
ax.grid(alpha=0.2)
plt.show()

print(
    "Owner technical evidence records:",
    sum("kengen_technical_assertions" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "ERA 2023 assertion records:",
    sum("era_2023_assertions" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "ERA historical project identities:",
    sum("era_planned_inventory" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "Nepal DoED reviewed licence identities:",
    sum("doed_inventory" in json.loads(r["extensions_json"]) for r in rows),
)
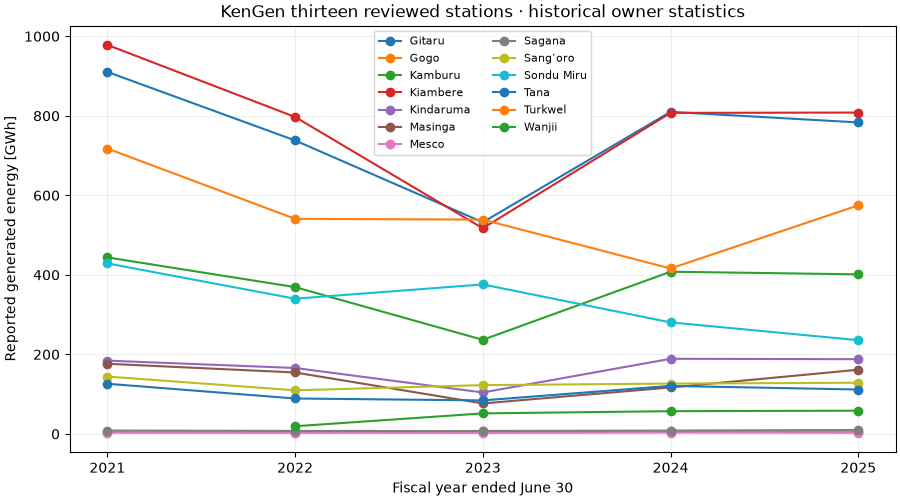
KenGen dated generation observations: 65
Owner technical evidence records: 12
ERA 2023 assertion records: 32
ERA historical project identities: 21
Nepal DoED reviewed licence identities: 227
Report evidence availability, not the sum of overlapping licence ratings.
doed_observations = [
    observation
    for row in rows
    for observation in json.loads(row.get("observations_json") or "[]")
    if observation["field"] == "licensed_capacity_mw"
]
print("DoED licensed-MW observations (not installed MW):", len(doed_observations))
print(
    "DoED observation periods (page update or retrieval basis; see uncertainty):",
    pd.Series([o["period"] for o in doed_observations]).value_counts().sort_index().to_dict(),
)

print(
    "NZ owner technical records:",
    sum("nz_owner_technical_assertions" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "NVE registry assertion records:",
    sum("nve_registry_assertions" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "NVE supplemental registry records:",
    sum("nve_registry_supplement" in json.loads(r["extensions_json"]) for r in rows),
)

# Completeness within linked identities; price areas are not grid connections.
for field in ("RegineNr", "ElspotomraadeNummer"):
    linked = [r for r in rows if "nve" in json.loads(r["external_ids_json"])]
    count = sum(
        any(
            fact["key"] == field
            for key in ("nve_registry_assertions", "nve_registry_supplement")
            for fact in json.loads(r["extensions_json"]).get(key, {}).get("facts", [])
        )
        for r in linked
    )
    print(f"NVE linked-subset {field} evidence: {count}/{len(linked)}")

print(
    "Norwegian owner-reviewed identities:",
    sum("norway_owner_assertions" in json.loads(r["extensions_json"]) for r in rows),
)

print(
    "Pumped-storage identities (capacity scope may remain unresolved):",
    sum(r["technology"] in {"pumped_storage", "mixed_pumped_storage"} for r in rows),
)
DoED licensed-MW observations (not installed MW): 227
DoED observation periods (page update or retrieval basis; see uncertainty): {'2026-10-15': 145, '2026-11-06': 82}
NZ owner technical records: 12
NVE registry assertion records: 188
NVE supplemental registry records: 160
NVE linked-subset RegineNr evidence: 188/188
NVE linked-subset ElspotomraadeNummer evidence: 188/188
Norwegian owner-reviewed identities: 28
Pumped-storage identities (capacity scope may remain unresolved): 3
Total running time of the script: (0 minutes 3.535 seconds)